
Fivetran Connector SDK Production Guide: State, Retries and Restart Safety
A runnable Fivetran Connector SDK example that fails mid-sync, restarts from its last checkpoint, and proves no rows were lost or duplicated, with every vendor behavior cited.
TL;DR / Key Takeaways
- Production-grade here means one testable property: after a sync fails and restarts, every source row is in the destination exactly once, with current values.
- Fivetran writes data between checkpoints atomically and gives the next sync the last checkpointed state, so restart safety comes down to what you put in state and when you checkpoint.
- Declare a primary key, use a compound
(updated_at, id)cursor, advance it only after the row is sent, and checkpoint at page boundaries. - The runnable example fails on page 3, restarts, and reconciles 250 of 250 rows on Fivetran's own Local Tester. Three deliberately broken variants lose or duplicate rows, and the tests catch each one.
A production-grade Fivetran Connector SDK connector is one you can kill halfway through a sync and restart without losing or duplicating a row. This guide builds a small connector that does that, fails it on purpose, and checks the result row by row against Fivetran's Local Tester. Every Fivetran behavior it relies on links to the documentation it came from, checked on October 11, 2026.
If you would rather have this built and supported for a source you depend on, that is our custom Fivetran SDK connector service.
What production-grade means here
"Production-grade" is usually a feeling. Here it is a short list of properties, each with a check that fails when the property breaks.
| Property | How the example checks it |
|---|---|
| No lost rows after a failed sync | Fail on page 3, restart, reconcile by primary key: missing ids must be empty |
| No duplicate primary keys | Same reconciliation: duplicate ids must be empty |
| Updated records hold current values | stale ids must be empty after an incremental sync |
| Transient errors retried, permanent errors fail fast | Unit tests on 503, Retry-After and 401 behavior |
| A new source column lands without breaking the sync | Snapshot 2 adds a priority column |
It does not cover deletes, production volume, or Fivetran's production scheduler. Those are in limits of the example.
Versions used: Connector SDK 2.12.1 (the latest release on PyPI on October 11, 2026), Local Tester 2.26.0908.001, Python 3.12.3. Fivetran currently supports Python 3.10 through 3.14 for deployed connectors (SDK runtime).
Run the example
The source is a synthetic, deterministic "tickets" API. There are no credentials, no network calls to a real API, and no customer data. The unit tests need only Python 3.10 or newer.
mkdir fivetran-restart-safety && cd fivetran-restart-safety
base=https://itsmorethansoftware.com/examples/fivetran-restart-safety
for f in README.md source.py sync.py connector.py emulated_destination.py \
    reconcile.py check_warehouse.py test_restart_safety.py test_negative_controls.py \
    configuration.json configuration.fail.json configuration.snapshot2.json requirements-dev.txt; do
  curl -fsSO "$base/$f"
done
python3 -m unittest -v
To run the same scenario on Fivetran's Local Tester, install the pinned SDK and follow the sequence below. The first fivetran debug downloads the tester, which was about 244 MB for version 2.26.0908.001.
python3 -m venv .venv
. .venv/bin/activate
pip install -r requirements-dev.txt
fivetran debug --configuration configuration.fail.json
python check_warehouse.py --snapshot 1
fivetran debug --configuration configuration.json
python check_warehouse.py --snapshot 1
fivetran debug --configuration configuration.snapshot2.json
python check_warehouse.py --snapshot 2
fivetran reset --yes
Minimal connector architecture
A Connector SDK connector needs an update(configuration, state) function and a Connector object. schema(configuration) is optional, but it is where you declare primary keys, and most production connectors need it (supported methods, required declarations). Since SDK 2.0.0, op.upsert() and op.checkpoint() no longer need yield (state management).
The example keeps the SDK at the edge. connector.py is the only file that imports it:
def update(configuration: dict, state: dict):
    api = SyntheticTicketsApi.from_configuration(configuration)
    stats = sync_tickets(
        api,
        state,
        op,
        page_size=int(configuration.get("page_size", "50")),
        base_delay=float(configuration.get("retry_base_seconds", "1")),
        log=log.info,
    )
    log.info(f"sync finished: {stats}")


connector = Connector(update=update, schema=schema)
| File | Role |
|---|---|
source.py |
Synthetic paginated API with injectable 503, Retry-After, 401 and page-replay faults |
sync.py |
Cursor, pagination, retries and checkpoints. No SDK import |
connector.py |
Wires sync.py to the SDK's Operations and Logging |
emulated_destination.py |
In-memory stand-in for four documented upsert and checkpoint behaviors, for fast unit tests |
reconcile.py |
Compares destination rows to the source by primary key |
check_warehouse.py |
Runs that comparison against the Local Tester's files/warehouse.db |
Keeping sync.py free of the SDK means the unit tests run in about 0.2 seconds with the standard library, and the same function runs unchanged under fivetran debug.
State and checkpoint model
These are the Fivetran behaviors restart safety depends on, all from the state management and operations references:
- State is a JSON dictionary you design. Fivetran passes the last saved state to
update()at the start of every sync, whether the previous sync succeeded or ended with an error. op.checkpoint(state=...)replaces the stored state and tells Fivetran the data sent so far can be written. Changing the state dictionary without checkpointing persists nothing.- Data between checkpoints is written atomically. If a sync fails, data processed after the last checkpoint may not be written.
- State is empty (
{}) on the first sync and after a full re-sync, so a missing cursor should mean "start from the beginning", not an error. - When several records can share a timestamp, Fivetran recommends a compound cursor such as
{ "updated_at": ..., "id": ... }. - State is capped at 10 MB and must not hold secrets or personal data.
The example stores one compound cursor under a versioned key, following Fivetran's advice to version keys when the state structure changes:
{"tickets_cursor_v1": {"updated_at": "2026-01-01T00:33:00Z", "id": 100}}
It validates that shape before trusting it, which the same page calls defensive state reads:
def read_cursor(state):
    """Return the (updated_at, id) cursor, or the start cursor on a first sync."""
    saved = state.get(STATE_KEY)
    if saved is None:
        return START_CURSOR
    if (
        not isinstance(saved, dict)
        or not isinstance(saved.get("updated_at"), str)
        or not isinstance(saved.get("id"), int)
    ):
        raise SyncFailed(f"state[{STATE_KEY!r}] has an unexpected shape: {saved!r}")
    return saved["updated_at"], saved["id"]
The example checkpoints after every 50-row page because its pages are tiny. On a long production sync, Fivetran's guidance is to checkpoint at page or batch boundaries, roughly every 10 minutes, and not more than once a minute.
Pagination
The synthetic API follows a common REST shape: updated_since is inclusive, results are ordered by (updated_at, id), and next_page_token is opaque and only valid inside the query that issued it. Records arrive in bursts of three with the same updated_at, so page boundaries regularly split a group of equal timestamps.
The sync loop does four things in a fixed order: fetch a page, skip anything at or before the cursor, upsert and advance the cursor one record at a time, then checkpoint.
    while True:
        page = call_with_retries(
            lambda: api.list_tickets(updated_since=updated_since, page_token=page_token, limit=page_size),
            max_attempts=max_attempts,
            base_delay=base_delay,
            sleep=sleep,
            log=log,
        )
        stats["pages"] += 1

        for record in page.records:
            key = (record["updated_at"], record["id"])
            if key <= cursor:
                # updated_since is inclusive, and a replayed page repeats rows.
                stats["skipped_replays"] += 1
                continue
            ops.upsert(table=TABLE, data=record)
            stats["upserts"] += 1
            cursor = key

        ops.checkpoint(state={STATE_KEY: {"updated_at": cursor[0], "id": cursor[1]}})
        stats["checkpoints"] += 1
Two rules come out of that loop:
- Store the cursor of the last record you sent, never the page token. A restart issues a fresh query from the cursor and does not depend on a token still being valid.
- Fix the query parameters for the whole sync. The first version of this example re-read the cursor on every page request, so
updated_sincechanged mid-query while the page token still came from the original query. The replay test caught it. The synthetic API now rejects that combination with an HTTP 400 so the mistake fails loudly.
Retry and transient failures
Fivetran's error handling guidance sorts failures into retry, warn and continue, or fail the sync. The example implements the retry and fail cases:
| Source response | Fivetran's guidance | Example behavior |
|---|---|---|
| HTTP 429 | Retry and honor any Retry-After header | retry_after overrides backoff |
| HTTP 5xx | Retry with backoff | 1s, 2s, 4s, then fail the sync |
| Timeout or dropped connection | Retry; if it continues, reduce batch or page size | Treated as transient |
| HTTP 401 or 403 | Fail fast with a clear configuration message | No retry, sync fails |
| Other 4xx | Fail fast with the status code and response body | No retry, sync fails |
def call_with_retries(request, *, max_attempts, base_delay, sleep, log):
    """Retry TransientSourceError with exponential backoff or Retry-After."""
    for attempt in range(1, max_attempts + 1):
        try:
            return request()
        except TransientSourceError as exc:
            if attempt == max_attempts:
                raise SyncFailed(f"{exc}: still failing after {max_attempts} attempts") from exc
            delay = exc.retry_after if exc.retry_after is not None else base_delay * 2 ** (attempt - 1)
            log(f"{exc}: attempt {attempt}/{max_attempts}, retrying in {delay:g}s")
            sleep(delay)
        except PermanentSourceError as exc:
            raise SyncFailed(f"{exc}: not retryable, check credentials and request") from exc
SyncFailed subclasses RuntimeError. An unhandled exception fails the sync and shows the stack trace in the dashboard; op.error() does the same with a message you control (logging, operations). Retries cover a blip inside one sync. Once they are exhausted, restart safety takes over.
Restart safety
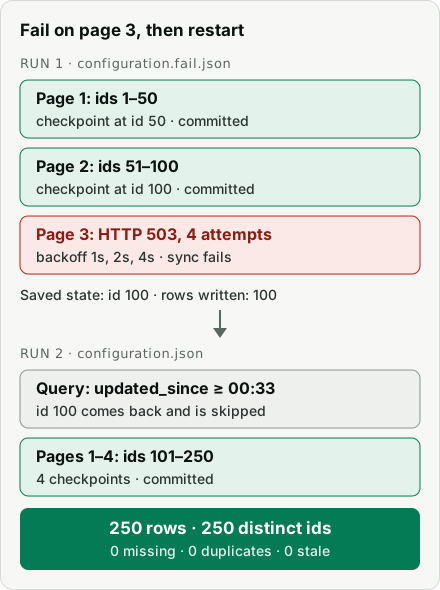
This is the Local Tester running configuration.fail.json, where page 3 returns HTTP 503 on four consecutive attempts. Lines are copied from the run, with the long failure message trimmed:
18:13:17.696 INFO     ⚡ connector page 1: checkpoint at id 50 (50 upserts so far)
18:13:17.713 INFO     ⚡ connector page 2: checkpoint at id 100 (100 upserts so far)
18:13:17.714 INFO     ⚡ connector HTTP 503 on page 3: attempt 1/4, retrying in 1s
18:13:18.715 INFO     ⚡ connector HTTP 503 on page 3: attempt 2/4, retrying in 2s
18:13:19.117 INFO     ⚡ debugger  checkpoint recorded: {"tickets_cursor_v1": {"updated_at": "2026-01-01T00:16:00Z", "id": 50}}
18:13:20.160 INFO     ⚡ debugger  checkpoint recorded: {"tickets_cursor_v1": {"updated_at": "2026-01-01T00:33:00Z", "id": 100}}
18:13:20.715 INFO     ⚡ connector HTTP 503 on page 3: attempt 3/4, retrying in 4s
18:13:24.740 SEVERE   ⚡ sdk       failed while executing update() error: HTTP 503 on page 3: still failing after 4 attempts
18:13:24.817 SEVERE   ⚡ debugger  SYNC FAILED — elapsed 00:00:09
The warehouse now holds what the two checkpoints committed, and the reconciliation says so. A failing check is the correct result at this point:
$ python check_warehouse.py --snapshot 1
expected rows:   250
rows present:    100
missing ids:     101-250
unexpected ids:  none
duplicate ids:   none
stale ids:       none
result:          FAIL
The restart with configuration.json starts from the saved cursor. Because updated_since is inclusive, id 100 comes back once and is skipped:
18:13:40.915 INFO     ⚡ connector page 1: checkpoint at id 149 (49 upserts so far)
18:13:40.928 INFO     ⚡ connector page 2: checkpoint at id 199 (99 upserts so far)
18:13:40.941 INFO     ⚡ connector page 3: checkpoint at id 249 (149 upserts so far)
18:13:40.946 INFO     ⚡ connector page 4: checkpoint at id 250 (150 upserts so far)
18:13:40.946 INFO     ⚡ connector sync finished: {'pages': 4, 'upserts': 150, 'skipped_replays': 1, 'checkpoints': 4}
18:13:44.248 INFO     ⚡ debugger  SYNC SUCCEEDED — total elapsed 00:00:05
$ python check_warehouse.py --snapshot 1
expected rows:   250
rows present:    250
missing ids:     none
unexpected ids:  none
duplicate ids:   none
stale ids:       none
result:          OK
On success, the Local Tester logs "Final checkpoint: committing any remaining operations". The example still checkpoints explicitly after its last page, and the emulated destination used by the unit tests rejects a sync that does not.
The duplicate and lost-row test
The unit tests run the same scenarios against emulated_destination.py, an in-memory stand-in that encodes four documented behaviors: upsert by primary key, _fivetran_id hashing when no key is declared, NULL handling for new and missing columns, and atomic commit at checkpoints. It is not Fivetran, and where the docs say data after the last checkpoint "may not be written", it takes the strict reading and discards it.
$ python3 -m unittest
...............
----------------------------------------------------------------------
Ran 15 tests in 0.165s

OK
Ten tests cover the correct connector: clean run, retry with backoff, Retry-After, fail-fast on 401, failure, restart, replayed page, full re-sync with empty state, incremental sync with a new column, and malformed state. Two more check the emulator itself. Every scenario that should finish with complete data ends with a reconciliation by primary key, the same comparison check_warehouse.py runs:
    return Reconciliation(
        expected=len(expected),
        present=len(rows),
        missing=sorted(set(expected) - set(seen)),
        unexpected=sorted(set(seen) - set(expected)),
        duplicate_keys=sorted(k for k, found in seen.items() if len(found) > 1),
        stale=sorted(
            k
            for k, found in seen.items()
            if k in expected
            and len(found) == 1
            and any(found[0].get(col) != value for col, value in expected[k].items())
        ),
    )
A test that has never failed proves little, so the last three tests implement plausible bugs and assert that the reconciliation catches them:
| Broken variant | What happens | Reconciliation result |
|---|---|---|
Timestamp-only cursor with > |
Ids 100, 101 and 102 share updated_at 00:33. The checkpoint stopped at 100, so the restart skips 101 and 102 |
missing ids: 101, 102 |
| Checkpoint before write | Page 2's rows are sent after its checkpoint, discarded when page 3 fails, and the cursor is already past them | missing ids: 51-100 |
| No primary key | Rows are keyed by _fivetran_id, a hash of the whole row, so updated tickets land as new rows |
duplicate ids: 10, 20, 30 |
The third case is the one Fivetran's schema() reference warns about. I also reintroduced the mid-query pagination bug and removed the replay filter by hand; the suite failed both times.
Schema-change considerations
Snapshot 2 updates tickets 10, 20 and 30 and adds tickets 251 to 280. Every touched record carries a new priority field. Sample input from the synthetic API:
{"id": 10, "updated_at": "2026-01-01T02:00:00Z", "subject": "Synthetic ticket 10", "status": "solved", "priority": "high"}
After fivetran debug --configuration configuration.snapshot2.json, the incremental sync sent 33 upserts, not 280, and the Local Tester's warehouse held:
| id | status | priority |
|---|---|---|
| 9 | open | NULL |
| 10 | solved | high |
| 251 | solved | normal |
That matches Fivetran's documented behavior (schema management, upsert):
- A new column is created with an inferred type, and existing rows get NULL. Older rows are not backfilled; a historical re-sync does that.
- A column the source stops sending stays in the table, with NULL in new rows.
- A renamed column arrives as a new column. Fivetran does not migrate the old one.
- Widening type changes are applied. Narrowing changes are not. A value that does not match a type declared in
schema()fails the sync. - Changing a primary key means backing up and dropping the table, then re-syncing it.
The example declares types only for the four columns it needs fixed and lets priority be inferred, which is what Fivetran recommends: declare columns only when you need a specific type.
Operational runbook
Where to look, from Fivetran's logging reference and building connectors overview:
- Connector SDK logs appear in the connection's logs tab, in the
CONNECTOR_SDK_LOGtable through the Fivetran Platform Connector, and in any external log service configured for the destination. log.warning()andlog.error()write to the sync logs only. To surface something on the dashboard, useop.warning()(up to 10 per sync) or fail withop.error()or an exception.- INFO logs are limited to 1,500 a minute and the excess is dropped, so log per page, not per record.
- State is not visible in the dashboard. Log it occasionally at checkpoints, or read and modify it through the connection state REST endpoints (state management).
- "Resync all historical data" clears state but does not mark destination rows deleted.
What to check in the warehouse, on a schedule:
-- The destination schema is named after the connection; the Local Tester uses "tester".
SELECT count(*) AS row_count, count(DISTINCT id) AS distinct_ids, max(updated_at) AS newest
FROM tester.tickets;
| Symptom | Likely cause | First action |
|---|---|---|
| Sync fails after exhausting retries | Source outage or rate limiting | Let the next sync resume from state; if it persists, reduce page size or move the schedule |
| Sync fails on 401 or 403 | Credentials or permissions | Fix configuration; nothing to resume |
| Fewer rows than the source | Timestamp-only cursor, or deletes the source does not expose | Reconcile by primary key, then check the cursor logic |
row_count above distinct_ids |
Missing or changed primary key | Fix schema(), back up and drop the table, re-sync |
| Every sync is a full reload | State key renamed or never checkpointed | Read state through the API; migrate old keys in update() |
newest falls behind the source |
Cursor stuck, or syncs failing quietly | Read the last checkpointed state and the SDK logs |
If a production connector already shows these symptoms and the cause is not obvious, that is what Pipeline Rescue is for: a fixed-scope diagnosis of the pipeline you already have.
Limits of the example
- The source is synthetic. A real API's ordering, filter inclusivity and page-token lifetime have to be confirmed against its documentation and real calls.
- No deletes. Capturing them needs
op.delete(),op.truncate()or a full refresh, and Fivetran notes many REST APIs do not expose deletes incrementally. - One table, one cursor. Multi-table connectors need a cursor per table so a single table can be re-synced.
- Offset pagination over data that changes during the sync is not modelled.
- The Local Tester runs on your machine. Fivetran notes it is slower than production and does not fully support schema-altering changes in incremental debug runs (local testing).
- No performance numbers. 250 synthetic rows prove correctness, not throughput.
When the native or vendor-assisted option is better
Check the native connector list first, and check that it covers the specific objects you need. If it does, it is cheaper than anything in this guide. The custom Fivetran connector vs Airbyte vs DIY comparison walks through that decision.
If there is no native connector, look at Fivetran's community connectors and SDK examples before starting from scratch. At the time of writing, Fivetran also advertises up to 60 days of free technical support from its Professional Services team for Connector SDK deployments (building connectors). If your team can own the connector afterwards, that is worth using.
A custom build is the right answer when the source matters, the API is awkward, and nobody in-house wants to own the state and failure handling. That is the work behind our custom Fivetran SDK connector service.
Related reading
- Workday SOAP APIs, custom connectors, and rate limits: where retry budgets and payload size dominate the design.
- CxAlloy API Extraction Guide: Request Signing, Nested Pagination, Rate Limits and Reconciliation: long syncs, where checkpoint cadence matters most.
- When a custom Fivetran SDK connector is the right answer
- Custom Fivetran connector vs Airbyte vs DIY
Sources
Fivetran documentation, checked October 11, 2026:
What we build in this area
Related practical notes
What to Automate First in a Small Business
If you are not sure where to start with automation, start with the task that wastes the most time and carries the least risk.
Read articleWhen Airflow Makes Sense for a Growing Business
Airflow is a workflow scheduler that keeps recurring data jobs reliable, visible, and recoverable when something goes wrong.
Read articleWhat Fivetran Connectors Do and Why Businesses Use Them
Fivetran moves data from your business systems into one place automatically. Here is what that means and when you need a custom connector.
Read article